Speech-to-Text API for Real-World Audio.
Transcribe audio with an independently-validated, accurate API, at a fraction of the cost. Trained on 500M+ hours of real-world conversations, Modulate's AI speech-to-text solution was built to handle noisy calls and complex audio environments.
Get immediate API access
400 hours free. Start transcribing in minutes.
"This transcription model might be the best stuff I've seen. I've never seen another model with realtime diarization (that works?!)"
Modulate beats competitors like Deepgram and Assembly AI on price, live stream diarization accuracy, and includes emotional context per utterance, which others don't offer.
"Integrating this API streamlined our workflow and significantly improved our voice recognition accuracy."
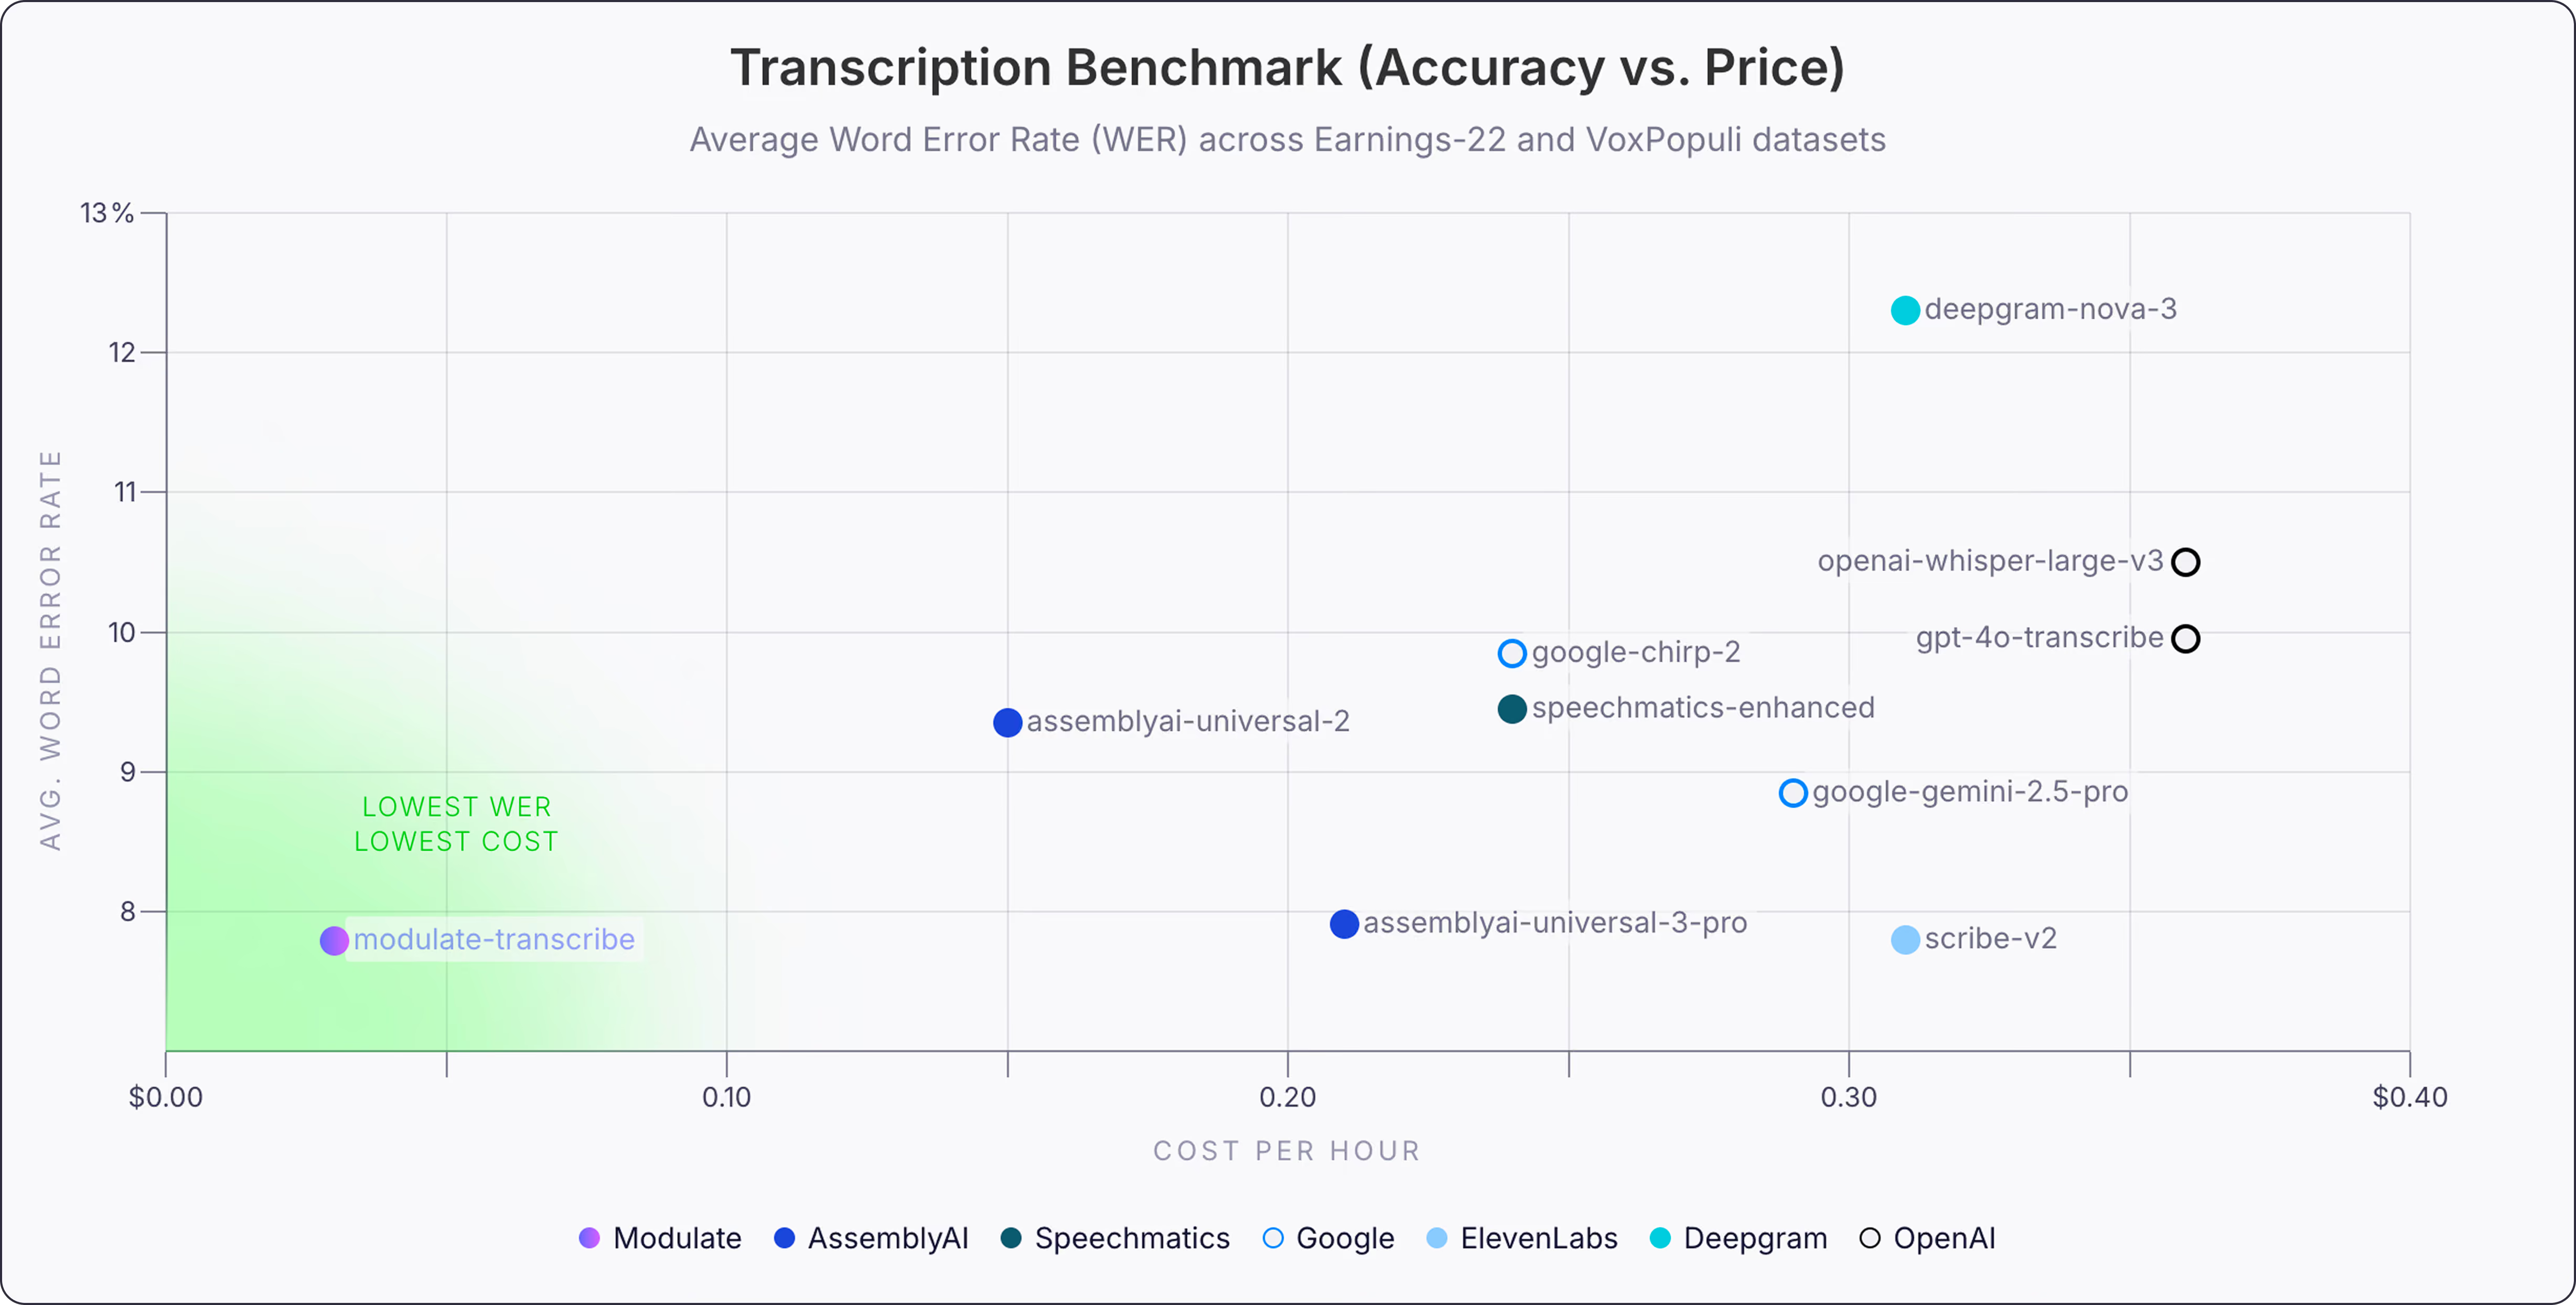
Where accuracy meets cost.
Tested on Earnings-22 and VoxPopuli, two of the industry's most widely used accuracy benchmarks. Modulate's transcription API achieves the lowest Word Error Rate at the lowest price per hour in the market.
One API. Real-time transcription & enrichment.
Batch and real-time streaming on the same API key. Capabilities that usually require separate models are built in and optional — no extra cost.


One curl. Full pipeline.
Send audio, get back a rich JSON response — utterances, speakers, languages, emotion, accent, and deepfake scores. All optional. All on the same endpoint.
curl --request POST \
  --url https://api.example.com/v1/audio/transcriptions \
  --header 'Authorization: Bearer YOUR_API_KEY' \
  --header 'Content-Type: application/json' \
  --header 'X-Request-ID: request_123456789' \
  --data '{
    "audio_url": "https://example.com/audio/customer-support-call.mp3",
    "model": "speech-understanding-v3",
    "language": "en",
    "features": {
      "speaker_detection": true,
      "speaker_labels": true,
      "emotion_detection": true,
      "sentiment_analysis": true,
      "accent_detection": true,
      "word_timestamps": true,
      "utterance_timestamps": true,
      "deepfake_detection": false
    },
    "transcription": {
      "format": "detailed",
      "punctuation": true,
      "normalize_text": true,
      "remove_filler_words": false,
      "max_speakers": 4
    },
    "metadata": {
      "customer_id": "customer_123456789",
      "conversation_id": "conversation_987654321",
      "source": "customer-support",
      "environment": "production"
    },
    "webhook": {
      "url": "https://example.com/webhooks/transcription-complete",
      "events": [
        "transcription.completed",
        "transcription.failed"
      ]
    }
}'{
"request_id": "req_01J8K2M4P7Q9R3S5T6V8W0XYZ",
"status": "completed",
"created_at": "2026-09-17T10:42:31.482Z",
"processing_time_ms": 1847,
"model": "speech-understanding-v3",
"language": {
"detected": "en",
"confidence": 0.9874,
"alternatives": [
{
"language": "es",
"confidence": 0.0082
},
{
"language": "fr",
"confidence": 0.0044
}
]
},
"audio": {
"duration_ms": 48750,
"sample_rate": 48000,
"channels": 2,
"format": "wav",
"file_name": "customer-support-conversation-recording-final-version.wav",
"source_url": "https://example.com/files/audio/customer-support-conversation-recording-final-version.wav"
},
"transcription": {
"text": "Hello, thank you for contacting our support team. How can I help you today? I am having an issue with my account and I would like to understand what happened.",
"confidence": 0.9642,
"word_count": 31,
"utterances": [
{
"utterance_uuid": "e5f6a7b8-c9d0-1234-efab-345678901234",
"speaker": 1,
"speaker_name": "Support Agent",
"text": "Hello, thank you for contacting our support team. How can I help you today?",
"start_ms": 0,
"end_ms": 6430,
"duration_ms": 6430,
"language": "en",
"emotion": "Neutral",
"sentiment": "Positive",
"confidence": 0.9821,
"accent": "American",
"deepfake_score": null
},
{
"utterance_uuid": "f6a7b8c9-d0e1-2345-fabc-456789012345",
"speaker": 2,
"speaker_name": "Customer",
"text": "Hi, I am having an issue with my account and I would like to understand exactly what happened with my most recent subscription payment.",
"start_ms": 6720,
"end_ms": 15420,
"duration_ms": 8700,
"language": "en",
"emotion": "Concerned",
"sentiment": "Negative",
"confidence": 0.9576,
"accent": "British",
"deepfake_score": 0.0021
},
{
"utterance_uuid": "a7b8c9d0-e1f2-3456-abcd-567890123456",
"speaker": 1,
"speaker_name": "Support Agent",
"text": "Of course. I can take a look at the account history and review the transaction details with you.",
"start_ms": 15900,
"end_ms": 22100,
"duration_ms": 6200,
"language": "en",
"emotion": "Helpful",
"sentiment": "Positive",
"confidence": 0.9731,
"accent": "American",
"deepfake_score": null
}
],
"words": [
{
"word": "Hello",
"start_ms": 0,
"end_ms": 420,
"confidence": 0.998
},
{
"word": "thank",
"start_ms": 450,
"end_ms": 720,
"confidence": 0.994
},
{
"word": "you",
"start_ms": 730,
"end_ms": 910,
"confidence": 0.999
},
{
"word": "for",
"start_ms": 940,
"end_ms": 1120,
"confidence": 0.991
},
{
"word": "contacting",
"start_ms": 1140,
"end_ms": 1780,
"confidence": 0.987
}
]
},
"analysis": {
"sentiment": {
"overall": "Neutral",
"score": 0.124,
"positive": 0.421,
"neutral": 0.382,
"negative": 0.197
},
"topics": [
{
"name": "Account Management",
"confidence": 0.942
},
{
"name": "Subscription Billing",
"confidence": 0.917
},
{
"name": "Customer Support",
"confidence": 0.886
}
],
"entities": [
{
"type": "product",
"value": "subscription",
"start_ms": 12400,
"end_ms": 13100,
"confidence": 0.932
},
{
"type": "financial_transaction",
"value": "payment",
"start_ms": 13600,
"end_ms": 14200,
"confidence": 0.911
}
],
"moderation": {
"flagged": false,
"categories": {
"harassment": false,
"hate": false,
"self_harm": false,
"sexual": false,
"violence": false
}
}
},
"metadata": {
"api_version": "2026-09-01",
"environment": "production",
"region": "us-east-1",
"organization_id": "org_example_123456789",
"project_id": "project_customer_voice_analysis",
"tags": [
"customer-support",
"production",
"speech-analysis",
"quality-assurance"
]
},
"usage": {
"audio_seconds": 48.75,
"input_tokens": 12847,
"output_tokens": 3942,
"total_tokens": 16789,
"billing": {
"currency": "USD",
"subtotal": 0.1847,
"tax": 0.0,
"total": 0.1847
}
}
}One API instead of five.
Stop stitching together separate transcription, diarization, and sentiment vendors. Get everything — speakers, emotion, accent, and PII redaction — from a single endpoint, in a single call.
Single-Endpoint Pipeline
- Full analysis in one call — diarization, PII redaction, emotion, and accent detection.
- 70+ languages supported out of the box with automatic language detection.
- Sub-350ms streaming latency with real-time partial transcripts and diarization.
- Simple pay-per-hour pricing at $0.03/hr with no hidden fees or rate-limit surprises.
Multi-Vendor Patchwork
- Separate services for transcription, diarization, and sentiment — each with its own SDK.
- Manual language routing adds latency and fails silently on unexpected dialects.
- Streaming requires a completely different integration path from batch processing.
- Tiered pricing across vendors makes cost forecasting unreliable at scale.
Authentic reviews from live projects.
Lorem ipsum dolor sit amet, consectetur adipiscing elit.
"Integrating this API streamlined our workflow and significantly improved our voice recognition accuracy."
"The comprehensive data returned allowed us to tailor our app’s responses dynamically and enhance user engagement."
"Reliable and fast — this service has become a core part of our audio processing pipeline."
One API instead of five.
Start transcribing in under 5 minutes. Full docs included.