Build voice AI that understands more than words
Voice AI Architecture: how to build real-time systems that capture what is said and how it is said
From Modulate, the team behind Velma and the Velma Voice Analytics API.
About the ebook
A transcript captures the words. It loses the tone, emotion, timing, and intent around them, which is often where the real risk or opportunity in a conversation sits.
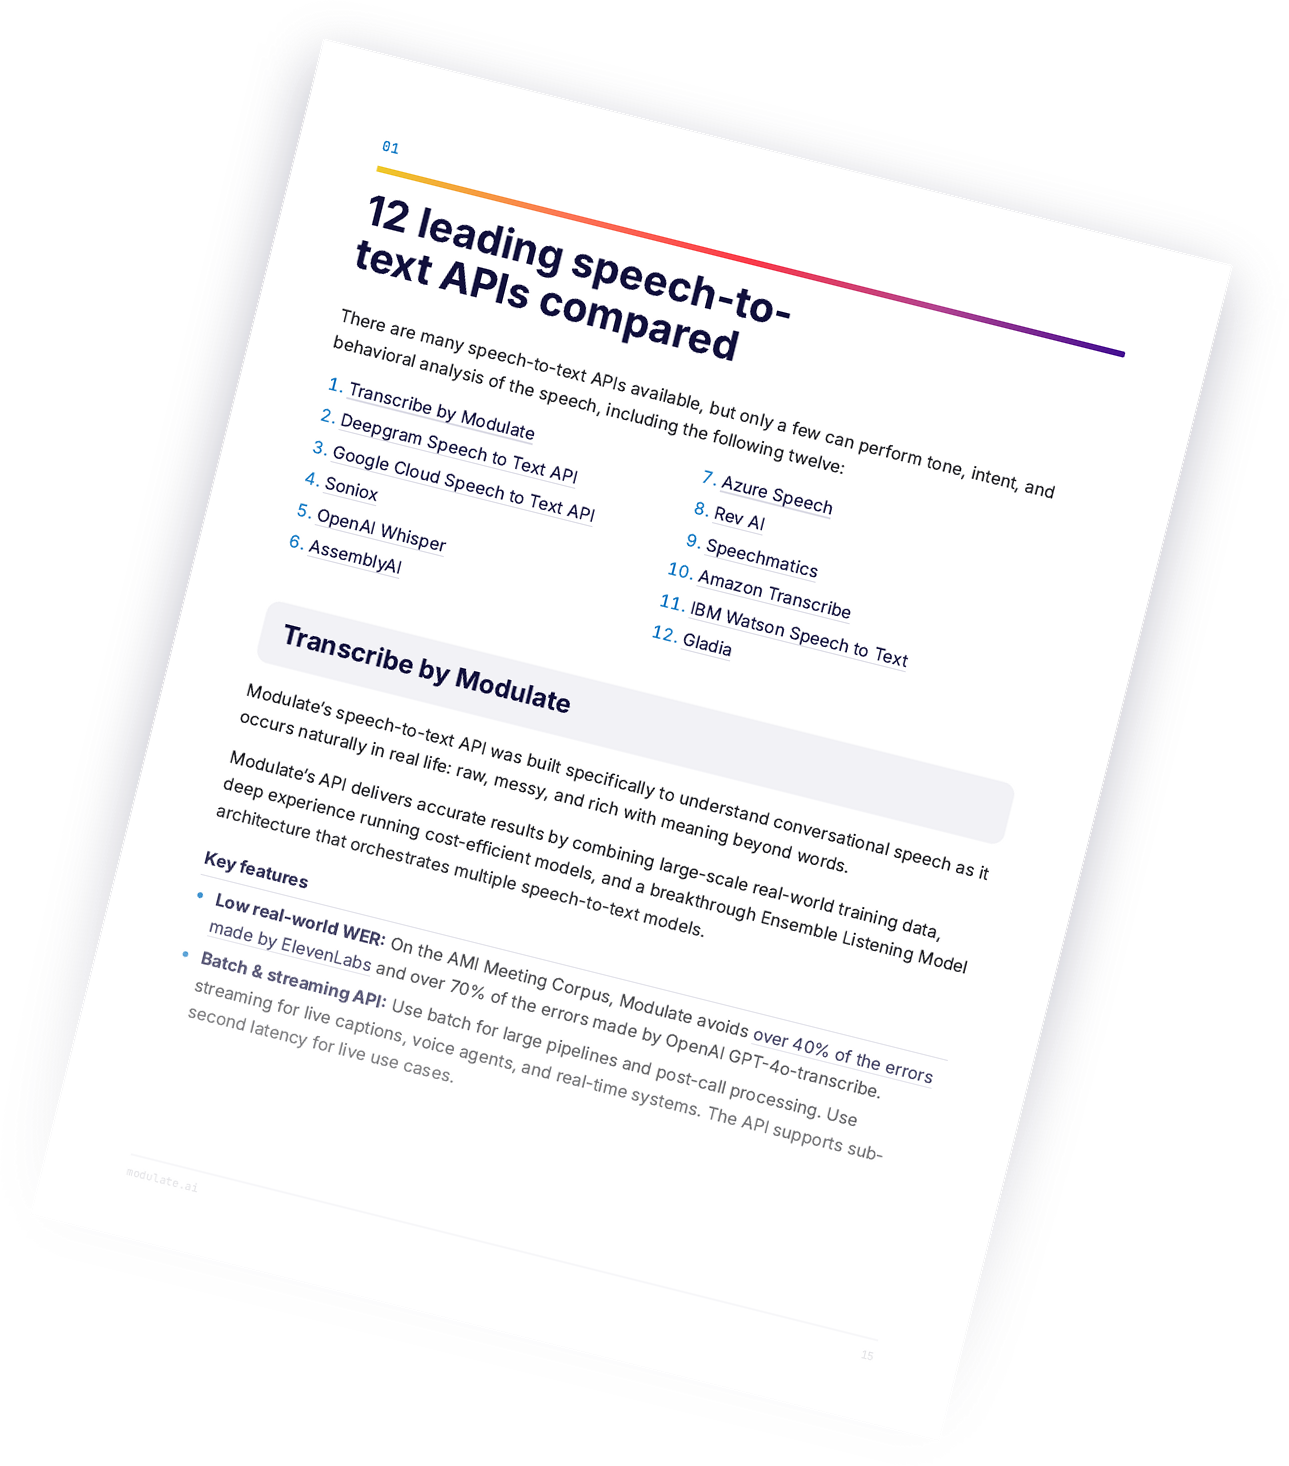
This ebook shows enterprise leaders where audio-native voice intelligence fits in a real-time voice AI architecture, and how combining transcription with acoustic, emotional, and behavioral signals surfaces what text-based systems miss.
It walks through how Modulate's Velma platform applies this across fraud and social engineering, customer experience, AI agent monitoring, employee safety, and compliance.
What you'll take away
Inside the ebook, you'll find:
Why converting conversations to text drops the tone, emotion, timing, and intent that signal risk
How an Ensemble Listening Model combines transcription with synthetic voice, emotion, prosody, and audio-event signals in one pass
How audio-native signals help surface deepfakes, impersonation, and coercion while a call is live
How an independent listener gives oversight of AI voice agents and human agents with the same models and events
Where real-time voice intelligence supports CX, employee safety, and policy compliance
Get the ebook
Get instant access to the Voice AI Architecture ebook: how to build real-time voice AI systems that understand more than words. No spam, just the ebook.
Instant PDF download
Five enterprise voice AI use cases
Example signals from a live call